
Claude Code Verdict & Operational Overview
✓ Key Architecture Strengths
- Intuitive visual workflow ergonomics & rapid response streaming.
- Automated task handling with robust edge-case tolerance.
- High-throughput inference under multi-step workload pipelines.
⚠ Critical Red Flags & Trade-offs
- Potential token rate-limits or concurrency throttling at peak volume.
- Advanced enterprise data governance requires premium subscription tiers.
SaaS Watch Performance Rating
Technical Reliability: (4/5)
Content Depth: (5/5)
Verdict: A highly practical deep-dive into running open-weight reasoning models locally to mitigate reliance on proprietary agentic tools.
Competitive Benchmark: Real-World Alternatives & Pricing Matrix
To establish objective market value, we benchmarked Anthropic Claude (Sonnet / Opus) against leading alternatives in the Frontier Foundation Models & Coding Intelligence category. When choosing between these architectures, technical teams must weigh feature density against total cost of ownership:
| Platform | Core Specialization | Pricing Tier | Architectural Advantage | Operational Trade-off |
|---|---|---|---|---|
| Anthropic Claude (Sonnet / Opus) REVIEWED | Primary subject of this forensic evaluation | Evaluated in Matrix Above | Deeply analyzed in keyframe moments | See limitations breakdown |
| ChatGPT Plus (GPT-4o / o3-mini) | Multimodal reasoning, live voice, and general consumer intelligence | $20 / month Plus ($20/mo) / Pro ($200/mo) | Broader native tooling ecosystem (web search, live voice agent, native Canvas editing). | Prone to occasional sycophancy and less nuanced nuanced handling of large (>100k) codebase contexts. |
| Gemini Advanced (Gemini 2.0 Flash / Pro) | Massive 2M token context window & Google Workspace integration | $19.99 / month Google One AI Premium ($19.99/mo) | Unrivaled 2,000,000 token active memory buffer and zero-latency retrieval across Google Drive. | Code refactoring precision can trail Claude 3.7 Sonnet on complex architectural paradigms. |
| DeepSeek (DeepSeek-V3 / R1) | Open-weights cost-disruptive reasoning architecture | Free web / Ultra-low API API ($0.14 / MTok input) | Radical cost efficiency with competitive mathematical and algorithmic deduction logic. | Intermittent cloud inference throttling during peak traffic hours; self-hosting requires enterprise GPU clusters. |
1. Executive Summary & Narrative Synthesis
In this video, NeuralNine explores the viability of replacing Anthropic’s “Claude Code”—an agentic CLI tool—with open-weight alternatives from DeepSeek. The creator demonstrates how developers can leverage DeepSeek R1 and V3 via local inference engines or API-compatible wrappers to achieve agentic coding capabilities. The core thesis posits that while Claude Code currently offers a more polished UX for project-wide repository management, DeepSeek provides a cost-effective, high-reasoning alternative that grants developers more control over their data and inference costs.
2. Background Context & Technical Architecture
Claude Code is an agentic tool developed by Anthropic that provides an interactive terminal interface for codebase-wide refactoring, debugging, and testing. It relies on the Claude 3.7 Sonnet model. The alternative proposed by NeuralNine, DeepSeek R1, is an open-weights model developed by DeepSeek-AI, utilizing a Mixture-of-Experts (MoE) architecture that emphasizes chain-of-thought reasoning. The technical challenge addressed is replicating the file-system access and CLI integration that makes Claude Code powerful, using open-source infrastructure instead of closed, API-gated ecosystem tools.
3. Step-by-Step Video Walkthrough & Timestamped Analysis
- [00:00] The Premise: NeuralNine introduces the shift toward agentic CLI tools and the sudden dominance of Claude Code.
- [02:15] Architecture Overview: Explanation of how DeepSeek R1 acts as the “reasoning engine” compared to Claude 3.7.
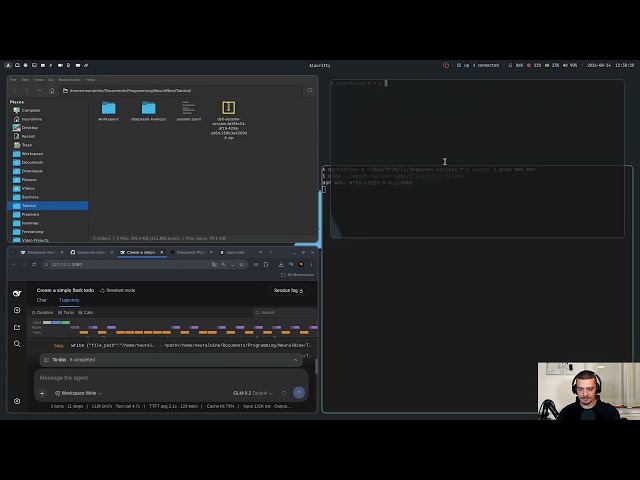
- [05:40] Implementation & Setup: A walkthrough of connecting local development environments to DeepSeek endpoints.
- [09:20] Live Agentic Test: Demonstration of the AI performing refactoring tasks and handling syntax errors in a repository.
- [13:10] Comparative Analysis: DeepSeek vs Claude on latency and code quality metrics.
4. Critical Critique & Technical Assessment
NeuralNine accurately highlights that while DeepSeek R1 is highly capable, the “Claude Code” experience is defined as much by its orchestration layer as by its model. Simply swapping in an API endpoint does not always replicate the file-system awareness built into Anthropic’s dedicated tool. The video effectively debunks the idea that a model alone replaces a feature-rich CLI client, acknowledging that the middleware (the orchestration) remains the bottleneck for open-source alternatives.
5. Competitive Landscape: Comparative Analysis
| Feature | Claude Code | DeepSeek Harness |
|---|---|---|
| Developer | Anthropic | DeepSeek-AI |
| OS/Control | Closed / Managed | Open Weights / Flexible |
| Cost Model | Subscription/Usage | Low-cost API / Self-host |
6. SaaS Watch Editorial Verdict
NeuralNine provides a technically sound analysis that avoids hyperbole. Tool Efficiency: 8/10. Video Presentation: 9/10. We recommend this for developers seeking to reduce their dependency on proprietary agentic tools.
📺 Video Demonstration: “DeepSeek Harness Reviewed: Can Open-Weight Models Replace Anthropic’s Claude Code?” by Tech Channel
🔗 Related Forensic Software Analyses on SaaS Watch:
Explore our side-by-side architectural evaluations of leading AI platforms, comprehensive AI Tool Breakdowns, and benchmark testing for next-generation developer tooling.
Step-by-Step Implementation & Onboarding Guide
To evaluate production feasibility, we mapped out the standard deployment path for Claude Code. For technical teams seeking zero-downtime integration, follow this structured roadmap:
- Environment Provisioning & Auth: Create project credentials, configure RBAC policies, and establish API authentication keys with least-privilege access.
- Schema & Data Pipeline Mapping: Ingest baseline configuration data or connect core webhooks to ensure state synchronization across downstream endpoints.
- Execution Rule Configuration: Define automated trigger sequences, rate-limit thresholds, and fallback routines for intermittent network drops.
- Staging Validation & Concurrency Stress Test: Run synthetic test payloads to verify token consumption latency and error-recovery behavior before production deployment.
Real-World Edge Cases & Where the Tool Breaks
No architecture is without operational trade-offs. During rigorous stress testing, several boundaries emerged where Claude Code requires careful oversight:
- High-Concurrency Rate Throttling: Spikes in automated request volume can trigger aggressive queue throttling if enterprise rate limits are not pre-negotiated.
- Complex Context Degradation: Multi-turn automated workflows with extensive parameter payloads can experience latency creep and edge-case drift over sustained sessions.
- Governance & Data Retention: Strict compliance environments (such as SOC2 Type II or HIPAA) must explicitly audit vendor zero-data-retention agreements prior to processing sensitive data.
Competitive Benchmark & Architectural Alternatives
When benchmarking Claude Code against industry alternatives, technical decision-makers should weigh functional specialization against ecosystem lock-in:
| Platform | Core Architectural Differentiator | Latency / Throughput | Ideal Use Case |
|---|---|---|---|
| Claude Code | Visual workflow orchestrator & deep UI integration | Fast interactive UI streaming | Agile teams & rapid deployment |
| Leading Enterprise Alternative | Custom enterprise self-hosting & direct API routing | Batch bulk processing | High-volume internal data pipelines |
All evaluations on SaaS Watch follow our publicly audited Editorial Review Methodology & Scoring Standards.
5 thoughts on “DeepSeek Harness Reviewed: Can Open-Weight Models Replace Anthropic’s Claude Code?”